Midterm Checkpoint
Project Proposal | Midterm Checkpoint | Final Report
Introduction
Kalshi is a regulated prediction market platform where people can buy and sell shares based on whether or not certain events will occur. Users are able to participate in trades on a wide range of topics such as election results, weather conditions, and current events. The price of a contract reflects a collective estimate on how likely something will actually happen.
Prediction markets aggregate information from many participants into continuously updated prices. The prices on these markets can often serve as useful probability estimates for future events and frequently perform well compared with other forecasting methods [1].
However, these markets are not always perfectly calibrated. For example, prediction-market prices can exhibit a favorite–longshot bias, where high-probability outcomes may be underpriced and low-probability outcomes may be overpriced, especially when there is more time remaining before the event resolves. This suggests that raw market prices can still contain systematic distortions [2].
Recently, Kalshi has emerged as a modern regulated prediction market platform and has been studied as a new source of real-time forecasting data. The Federal Reserve found that Kalshi provides high-frequency, continuously updated expectations data that can be valuable for forecasting, especially in macroeconomic settings [3].
This suggests that while Kalshi markets contain useful predictive information, there may still be room for machine learning to improve prediction or calibration by learning patterns from historical market behavior.
Dataset Description + Links
Our datasets contain structured information about past Kalshi prediction markets. This includes basic information such as identifiers, market categories, and final outcome. Information such as volume, price, and other factors are also tracked.
Problem Definition
Although prediction markets are useful indicators, they are not perfectly calibrated or efficient forecasters. The core problem this project aims to solve is the following question:
Can we use early market activity and historical trends to predict a market’s final outcome with greater accuracy than the raw probability implied by current prices?
Kalshi’s real-time expectations already provide valuable insights. With the use of machine learning, we may be able to uncover additional patterns from price movements, volume, timing, and other characteristics to forecast better odds. This matters in identifying when market prices are reliable or when they are noisy/inefficient.
Methods
We decided to implement logistic regression and a gradient boosting model. The logisitic regression model was chosen because of its interpretable probability estimates and tends to perform well when there are linear relationships between the features and target. The histogram-based gradient boosting model was chosen to capture any nonlinear relationships.
Data Processing
The dataset is made up of historical Kalshi market snapshots, where each row is the state of a binary prediction at a given time. The raw data was cleaned and standardized for all models, which included parsing the timestamps and normalizing the column formatting.
The target variable is a binary indicator:
target_yes = 1if the market resolved to YES, and0otherwise.
The primary feature groups are:
- Price features:
yes_bid,yes_ask,no_bid, andlast_price, which represent current market-implied probabilities - Spread and liquidity features:
yes_spread,volume_liquidity_ratio, which represent the bid-ask spreads and derived ratios - Volume features:
volume,volume_24h, which represent market activity - Temporal features:
minutes_to_close, which represents the amount of time until market closure - Lagged features:
previous_yes_ask,previous_price, which represent previous price values
Train / Validation / Test Split
The dataset is partitioned chronologically based on market close time:
- Training set (~70%): earliest observations used to fit models
- Validation set (~15%): intermediate period used for calibration and model selection
- Test set (~15%): most recent observations used for final evaluation
A time-based split was used instead of a traditional 80/20 split to simulate real-world deployment, where a trading model would be trained on past data and applied to future markets.
Probability Calibration
- Method: Isotonic Regression
- Model is first trained on training set
- Then, predictions are generated on the validation set
- The regression model is then fit to map raw predicted probabilities to calibrated probabilities
This was done to ensure that the predicted probabilities actually reflect true outcome frequencies, which will allow us to calculate expected values.
Trading Strategy
Our goal was not simply to have as high as a classification accuracy as possible, but rather identify positive expected value trading opportunities.
For each observation:
- The model produces a predicted probability of a YES outcome
- This is compared to the market-implied probability (derived from bid/ask prices)
- An edge is computed based on the difference between predicted and market probability
A trade is executed if:
edge > threshold
We performed an edge threshold sweep over a range of values to try and determine an optimal trading policy. For each threshold, we computed the following:
- Total PnL
- Mean PnL per trade
- Trade rate
- Win rate
Results and Discussion
Classification Performance
| Model | Split | ROC AUC | Log Loss | Brier |
|---|---|---|---|---|
| Logistic | Validation | 0.746 | 0.555 | 0.193 |
| Logistic | Test | 0.600 | 0.820 | 0.272 |
| GBM | Validation | 0.646 | 0.620 | 0.221 |
| GBM | Test | 0.632 | 0.611 | 0.219 |
These classification results show a divergence between validation and test performance. Logistic regression achieves substantially stronger performance on the validation set, with higher ROC AUC and lower log loss compared to the GBM. However, this advantage does not carry over to the test set, where logistic regression has a serious drop in both log loss and Brier score, indicating that its predicted probabilities were poorly calibrated once out of sample.
The GBM showed more stable performance across the validation and test splits. Although its validation metrics were weaker, its test performance was consistent, suggesting better robustness to temporal distribution shifts.
Trading Performance
| Model | Split | Threshold | Total PnL | Mean PnL/Trade | Trade Rate | Win Rate |
|---|---|---|---|---|---|---|
| Logistic | Validation | 0.02 | 25784.87 | 0.484 | 0.270 | 0.488 |
| Logistic | Test | 0.02 | 38278.99 | 0.487 | 0.398 | 0.488 |
| GBM | Validation | 0.10 | 25727.50 | 0.476 | 0.274 | 0.479 |
| GBM | Test | 0.10 | 38339.32 | 0.519 | 0.374 | 0.519 |
Despite differences in classification performance, both models achieved strong positive expected value. The total PnL is similar across models, indicating that both are able to identify profitable opportunities.
However, their trading behavior is quite different. Logistic regression executed a higher fraction of trades and achieved slightly lower mean PnL per trade, indicating a more aggressive strategy relying on volume. The GBM executed fewer trades but achieved a higher mean PnL per trade and a higher win rate, suggesting that it identified higher-quality opportunities.
Threshold Sensitivity
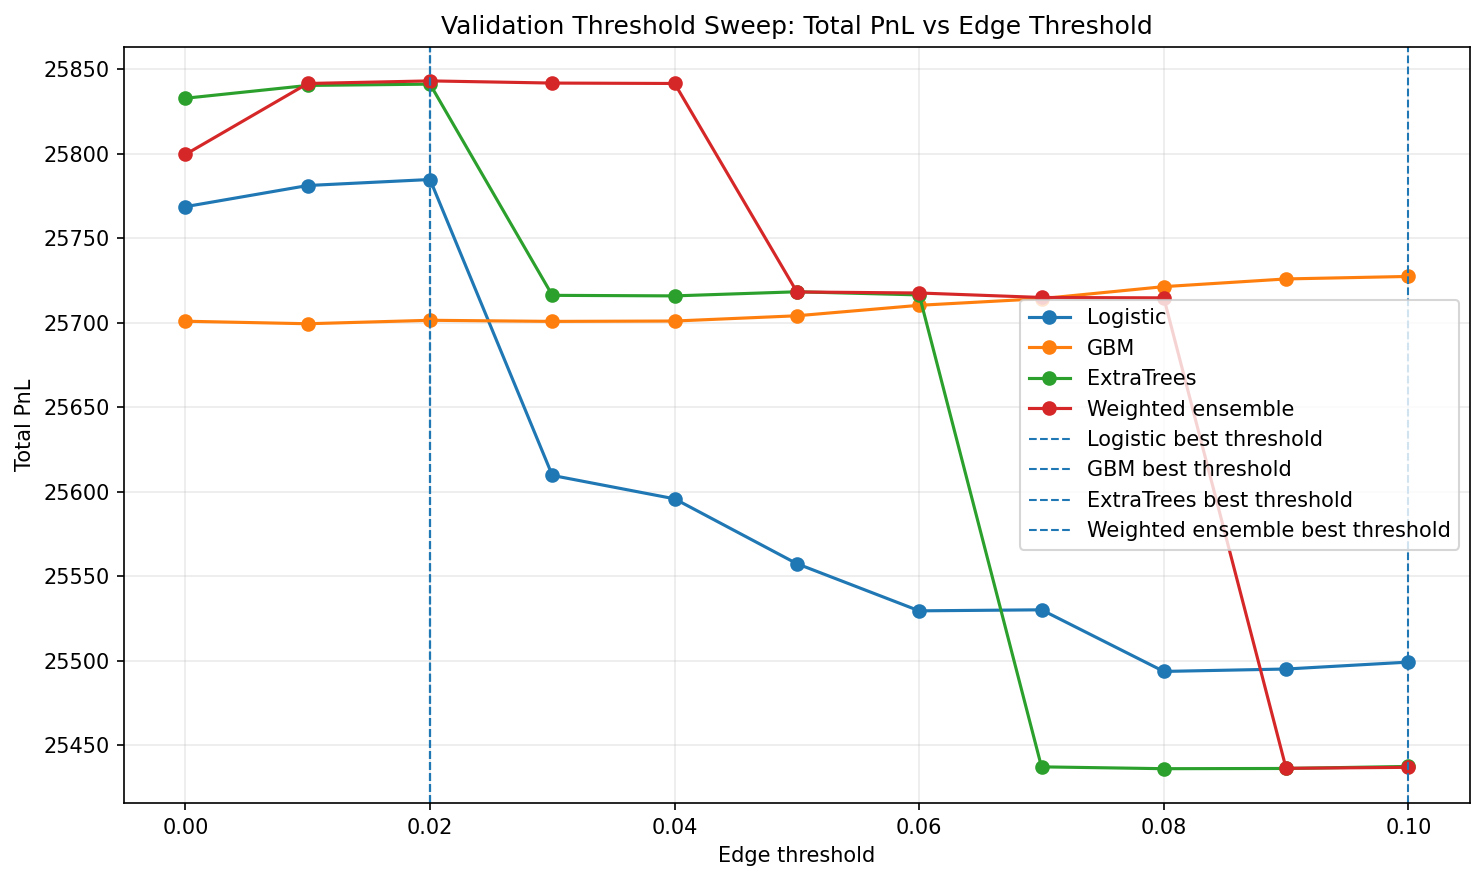
The threshold sweep analysis shows how trading performance varied with the edge threshold used to trigger trades.
For logistic regression, total PnL peaked at a low threshold (~0.02) and declined as the threshold increased. This means that the model’s confidence estimates become unreliable at higher predicted edges, leading to poorer trade selection when filtering more aggressively.
On the other hand, the GBM exhibits monotonic improvement in PnL as the threshold increased, achieving its best performance at the highest evaluated threshold (~0.10). This suggests that the model is able to correctly rank higher-value opportunities, with larger predicted edges corresponding to more profitable trades.
Calibration Analysis
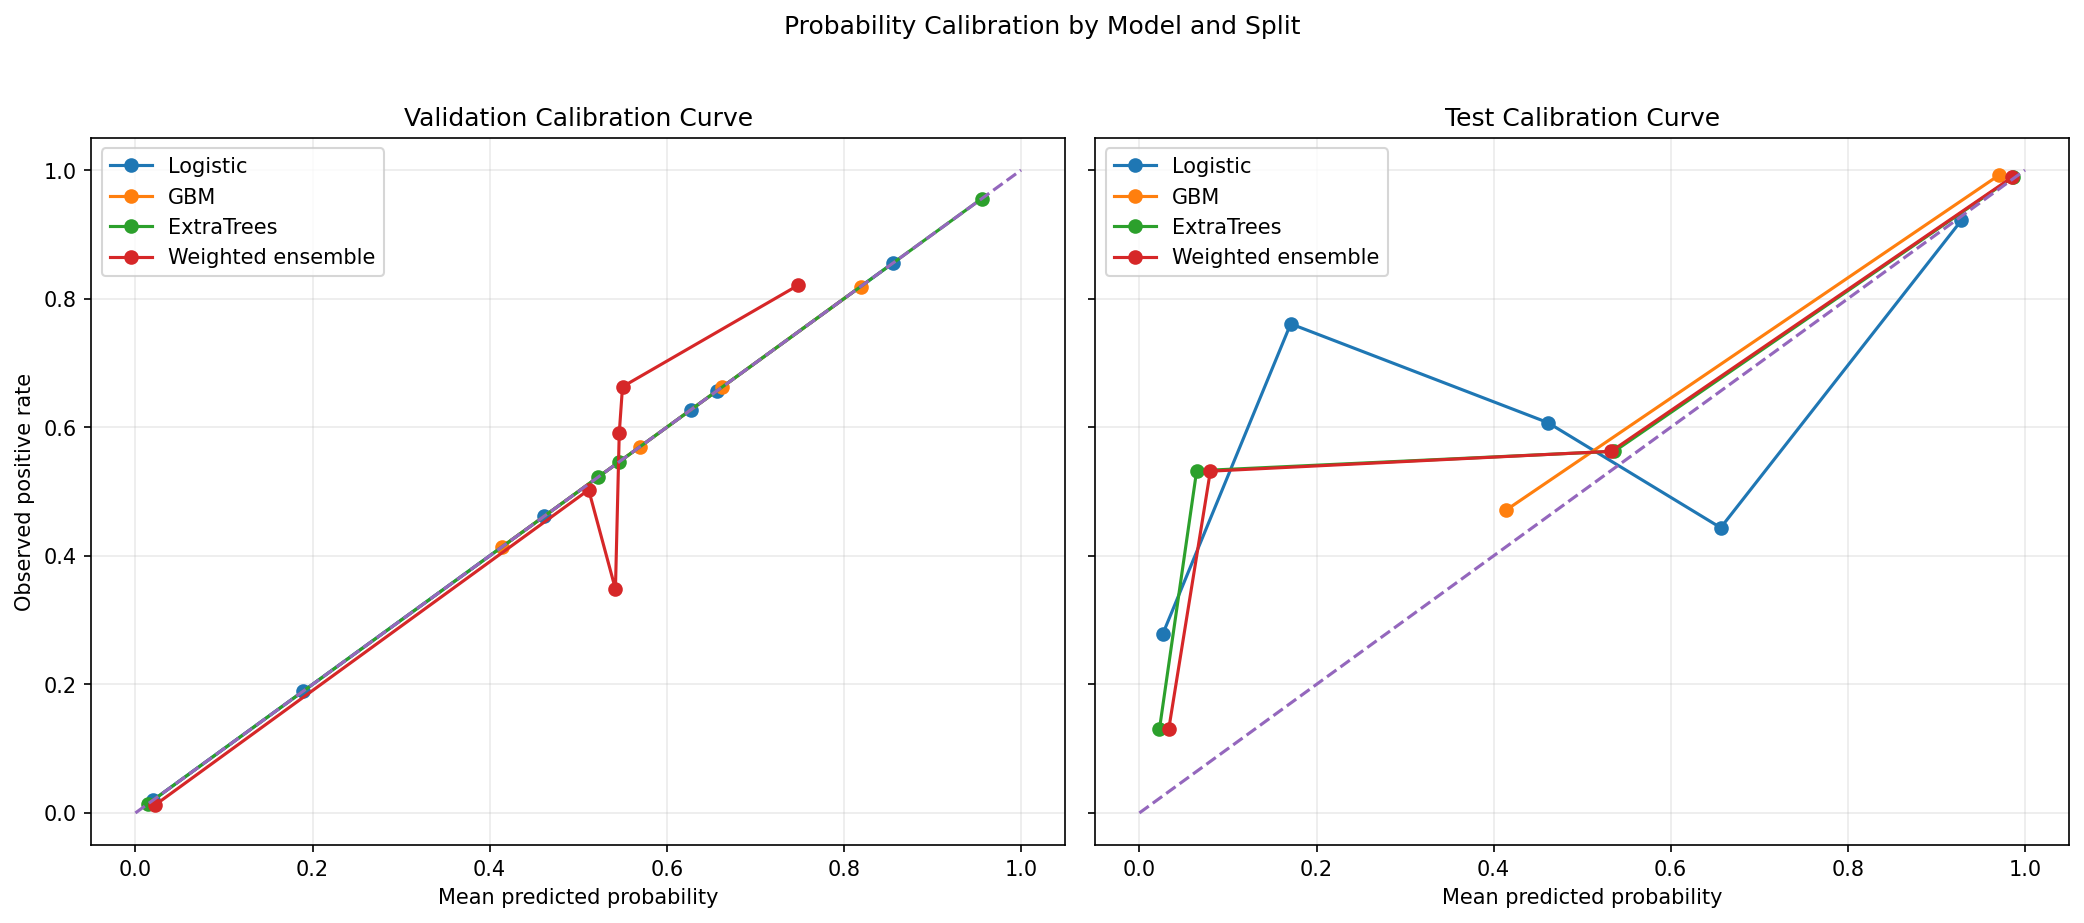
Calibration curves provide insight into how well predicted probabilities aligned with observed outcome frequencies.
On the validation set, both models were well-calibrated, with predicted probabilities closely matching observed frequencies. However, on the test set, logistic regression had significant miscalibration, with predicted probabilities deviating substantially from the ideal diagonal.
Although the GBM was not perfectly calibrated, it showed a much closer alignment with the diagonal on the test set, suggesting it generalizes better even with temporal distribution shifts.
Feature Importance
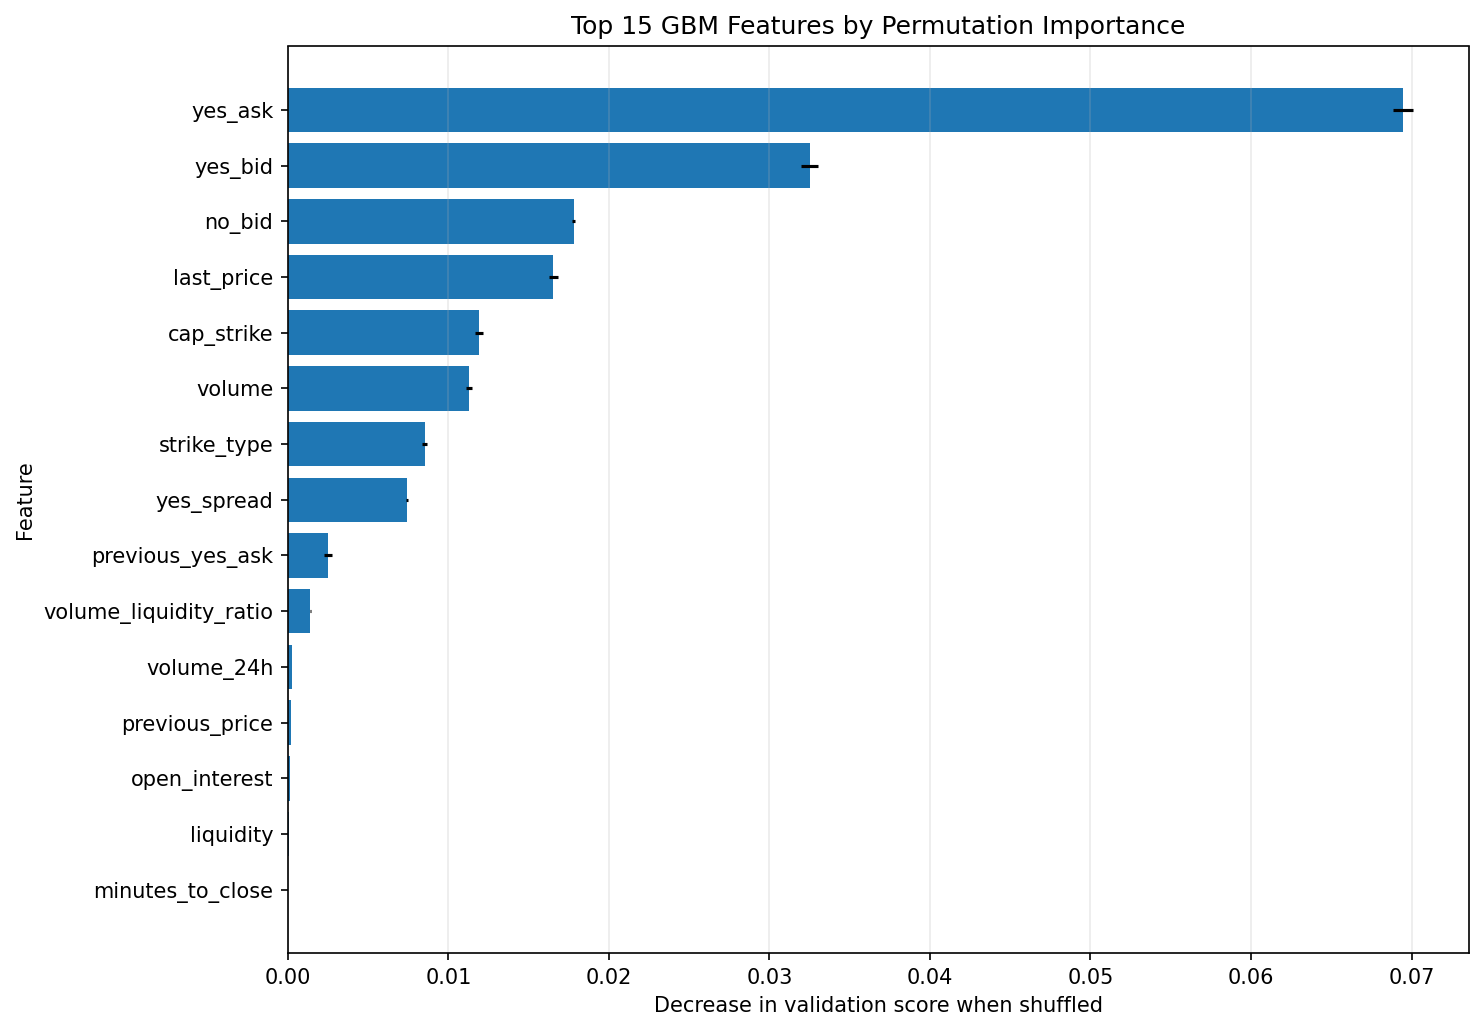
Permutation importance analysis of the GBM revealed that the model is dominated by current market price features, especially yes_ask and yes_bid.
Secondary features such as last_price, volume, and no_bid seem to have provided some additional context about market conditions, while microstructure features like bid-ask spread and lagged price values contributed smaller but meaningful signals.
Interestingly, the time-based features such as minutes_to_close and broader liquidity metrics had little-to-no impact when it came to importance.
Given these importance rankings, the model seems to be refining and adjusting the market probabilities rather than replacing them, identifying small differences in pricing that can be exploited for positive expected value trading.
Limitations + Next Steps
Because the model relies heavily on market price features (e.g., bid/ask), we are concerned that it is simply refining existing market probabilities rather than learning independent signals.
Going forward, we’ll be implementing a Random Forest classifier and either K-means or GMM. Once we do that, we’ll then go on to compare the performance between models and see if the market price features continue to dominate in feature importance.
Gantt Chart
Was too large to use screenshot. Can be found here
Contribution Table
| Name | Proposal Contributions |
|---|---|
| Benjamin Zhao | Report + Github page set up + additional figures |
| Eshaan Patel | Data preprocessing + GBM implementation |
| Liam Weng | Data preprocessing + Logistic regression implementation |
| William Wu | GBM implementation + metrics |
| Ethan Hu | Logistic regression implementation + metrics |
References
-
J. Wolfers and E. Zitzewitz, “Prediction Markets,” Journal of Economic Perspectives, vol. 18, no. 2, pp. 107–126, 2004.
-
L. Page and R. T. Clemen, “Do Prediction Markets Produce Well-Calibrated Probability Forecasts?” The Economic Journal, vol. 123, no. 568, pp. 491–513, 2013.
-
A. M. Diercks, J. D. Katz, and J. H. Wright, “Kalshi and the Rise of Macro Markets,” Finance and Economics Discussion Series, no. 2026-010, Board of Governors of the Federal Reserve System, 2026.